Dockerizing a RAG Application with FastAPI, LlamaIndex, Qdrant and Ollama
Update (October 2026): this post was revised after the original setup stopped building with recent versions of Docker Compose. The base image is now built through
additional_contexts, all images install dependencies fromuv.lockinto one shared virtual environment, the NVIDIA GPU configuration is optional, and the run steps ingest documents before starting the API.
Introduction
In the previous article, we built a local RAG api using FastAPI, LlamaIndex and Qdrant to query documents with the help of a local LLM running via Ollama.
While the application worked locally, setting it up each time, installing dependencies, ensuring the right versions in the right environment, running background services..quickly became tedious and error-prone.
In this post, we’ll walk through how we Dockerized the entire setup to make it fully containerized, reproducible, and easy to deploy with a single command. By the end, we’ll have a clean multi-service Docker Compose setup running this RAG app in isolated containers.
Project Structure Overview
So far this is the project structure of our project:
1
2
3
4
5
6
7
8
9
10
├── api/                     # FastAPI app
│   ├── main.py               # FastAPI entry point
│   └── rag.py                # RAG logic, used by the api
├── data/                    # Data ingestion / document handling
│   ├── data.py               # Script to download, load and process documents
├── ollama/                  # Local model setup with Ollama
│   ├── Modelfile             # Ollama model definition (e.g., Zephyr, llama2, mistral)
│   └── run_ollama.sh         # Script to start Ollama and serve the model
├── pyproject.toml           # Project metadata and dependencies
└── uv.lock                  # Lockfile with pinned dependency versions
Creating Dockerfiles
Dockerfiles contains the instructions on how to build the image, such as: base image, dependencies and commands to run.
To dockerize our entire application, we need to create a Dockerfile for each service.
In our case, we need to build two custom images:
- API image
- Data ingestion tool image
For Qdrant & Ollama, we only need to pull the official images and run them directly.
- Qdrant image: https://hub.docker.com/r/qdrant/qdrant
- Ollama image: https://hub.docker.com/r/ollama/ollama
Let’s first ensure our dependencies are defined correctly. Since we are using uv and pyproject.toml file to manage dependencies, the typical setup looks like this:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
[project]
name = "local-rag-llamaindex"
version = "0.1.0"
description = "Local llamaindex RAG api to assist researchers quickly navigate research papers"
readme = "README.md"
requires-python = ">=3.13"
dependencies = [
    "arxiv>=2.2.0",
    "fastapi[standard]>=0.115.12",
    "langchain>=0.3.24",
    "langchain-community>=0.3.22",
    "llama-index>=0.12.33",
    "llama-index-embeddings-huggingface>=0.5.3",
    "llama-index-embeddings-langchain>=0.3.0",
    "llama-index-llms-ollama>=0.5.4",
    "llama-index-vector-stores-qdrant>=0.6.0",
    "ollama>=0.4.8",
    "pydantic>=2.11.3",
    "pyyaml>=6.0.2",
    "qdrant-client>=1.14.2",
    "sentence-transformers>=4.1.0",
    "structlog>=25.3.0",
    "tqdm>=4.67.1",
]
One challenge is that a typical Dockerfile requires installing the necessary dependencies, which means copying the pyproject.toml file and installing everything listed in it.
However, since we only have a single dependencies file, and each service uses both common and unique libraries, it’s not a good practice to install all dependencies, including unused ones into every Docker image we build.
To address this, we’ll separate the dependencies as follows:
- Shared dependencies: Used by both services, e.g.,
llama-index,qdrant-client, etc. These will go into a base image. - API specific dependencies: e.g.,
FastAPI,ollama, etc. - Data ingestion tool dependencies: e.g.,
arxiv, etc.
To do that, we’ll keep the shared dependencies in the main dependencies section, and the service-specific ones under [project.optional-dependencies] in pyproject.toml:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
[project]
name = "local-rag-llamaindex"
version = "0.1.0"
description = "Local llamaindex RAG api to assist researchers quickly navigate research papers"
readme = "README.md"
requires-python = ">=3.13"
dependencies = [
    "hf-xet>=1.0.5",
    "llama-index>=0.12.33",
    "llama-index-embeddings-huggingface>=0.5.3",
    "llama-index-llms-ollama>=0.5.4",
    "llama-index-vector-stores-qdrant>=0.6.0",
    "python-dotenv>=1.1.0",
    "pyyaml>=6.0.2",
    "qdrant-client>=1.14.2",
    "sentence-transformers>=4.1.0",
    "structlog>=25.3.0",
]

[project.optional-dependencies]
data_ingest = [
    "arxiv>=2.2.0",
]
api = [
    "fastapi[standard]>=0.115.12",
    "pydantic>=2.11.3",
    "ollama>=0.4.8",
]
Base Image
This image will include all shared dependencies, mainly llama-index packages, qdrant and sentence-transformers, and it will be used as the base for both the API and data ingestion images.
1
2
3
4
5
6
7
8
9
10
FROM ghcr.io/astral-sh/uv:python3.13-bookworm-slim

ENV UV_PROJECT_ENVIRONMENT=/opt/venv \
    PATH="/opt/venv/bin:$PATH"

WORKDIR /app

COPY pyproject.toml uv.lock ./

RUN uv sync --frozen --no-install-project
We’re starting from the official uv image, which comes with python3.13 and uv pre-installed. It is a good starting point since we’ll be using pyproject.toml and uv for managing dependencies.
UV_PROJECT_ENVIRONMENT tells uv to create the virtual environment at a fixed location, /opt/venv, and adding it to PATH makes python and fastapi resolve to that environment, so we don’t need uv run later on. Every image built on top of this one will install into that same environment.
Next, we set up a working directory, in this case we called it app/, and then we copy our .toml and .lock files into it.
Finally, uv sync installs the shared dependencies (the main dependencies list, without any optional extras):
--frozeninstalls exactly the versions pinned inuv.lock, without re-resolving them.--no-install-projectinstalls only the dependencies, not our project itself as a package. Our code isn’t even in the image at this point, and the services run their scripts directly.
API Image
1
2
3
4
5
6
7
8
9
10
11
FROM rag-base-image

WORKDIR /app

RUN uv sync --frozen --no-install-project --extra api

WORKDIR /api

COPY api/ .

CMD ["fastapi", "run", "main.py", "--port", "80", "--host", "0.0.0.0"]
We start by using the base image we just created, meaning we won’t have to reinstall all the common dependencies.
We then install the api specific dependencies, found in pyproject.toml under [project.optional-dependencies], in the “api” section. The pyproject.toml and uv.lock files are already in /app from the base image, and uv sync compares the environment in /opt/venv with the lock file: the shared packages are already there, so it only adds the ones from the api extra.
Both the base image and this one must install into the same environment for this to work. If the child image installed its dependencies somewhere else (for example into the system Python with
uv pip install --system), it would download and install all the shared dependencies a second time.
Then we set /api as our working directory, so any relative paths after (e.g., in COPY instructions) will be based on that directory, and copy the local api/ folder into it.
Finally, we start the fastapi server on port 80.
Docker builds each instruction into an intermediate layer. If a layer hasn’t changed since the last build, Docker caches it, meaning it won’t re-run that step
If we only change the app code in api/, Docker won’t re-install dependencies, it’ll reuse the cached layer above.
That’s why we install dependencies before copying the project code: to avoid reinstalling packages every time we modify the code.
Data ingestion image
1
2
3
4
5
6
7
8
9
FROM rag-base-image

WORKDIR /app

RUN uv sync --frozen --no-install-project --extra data_ingest

COPY data/ .

ENTRYPOINT ["python", "data.py"]
This one is a bit similar to the api image, but this time we add the “data_ingest” extra (just arxiv), copy the data/ folder to the app/ directory in the container, then run the script with python data.py. Any arguments passed to the container are appended to this entrypoint.
Ollama image
For Ollama, we’ll directly use a prebuilt image ollama/ollama:latest, and since we want it to use a local llm with our created Modelfile, we need to provide some instructions to copy the correct file and run the LLM we created.
The Modelfile expects the model weights next to it, so download the Zephyr 7B Beta GGUF file (~5 GB) into the ollama/ folder:
1
2
curl -L -o ollama/zephyr-7b-beta.Q5_K_M.gguf \
  https://huggingface.co/TheBloke/zephyr-7B-beta-GGUF/resolve/main/zephyr-7b-beta.Q5_K_M.gguf
We’ll do that with the help of a simple bash script that will be used later in our docker compose file.
Qdrant image
Same as Ollama, we’ll use the prebuilt image qdrant/qdrant
Now that we have all our Dockerfiles ready, let’s go ahead and create a Docker Compose file that will orchestrate our multi-container setup.
Docker Compose
Now that each component of our RAG system has its own Dockerfile and image, it’s time to bring them all together.
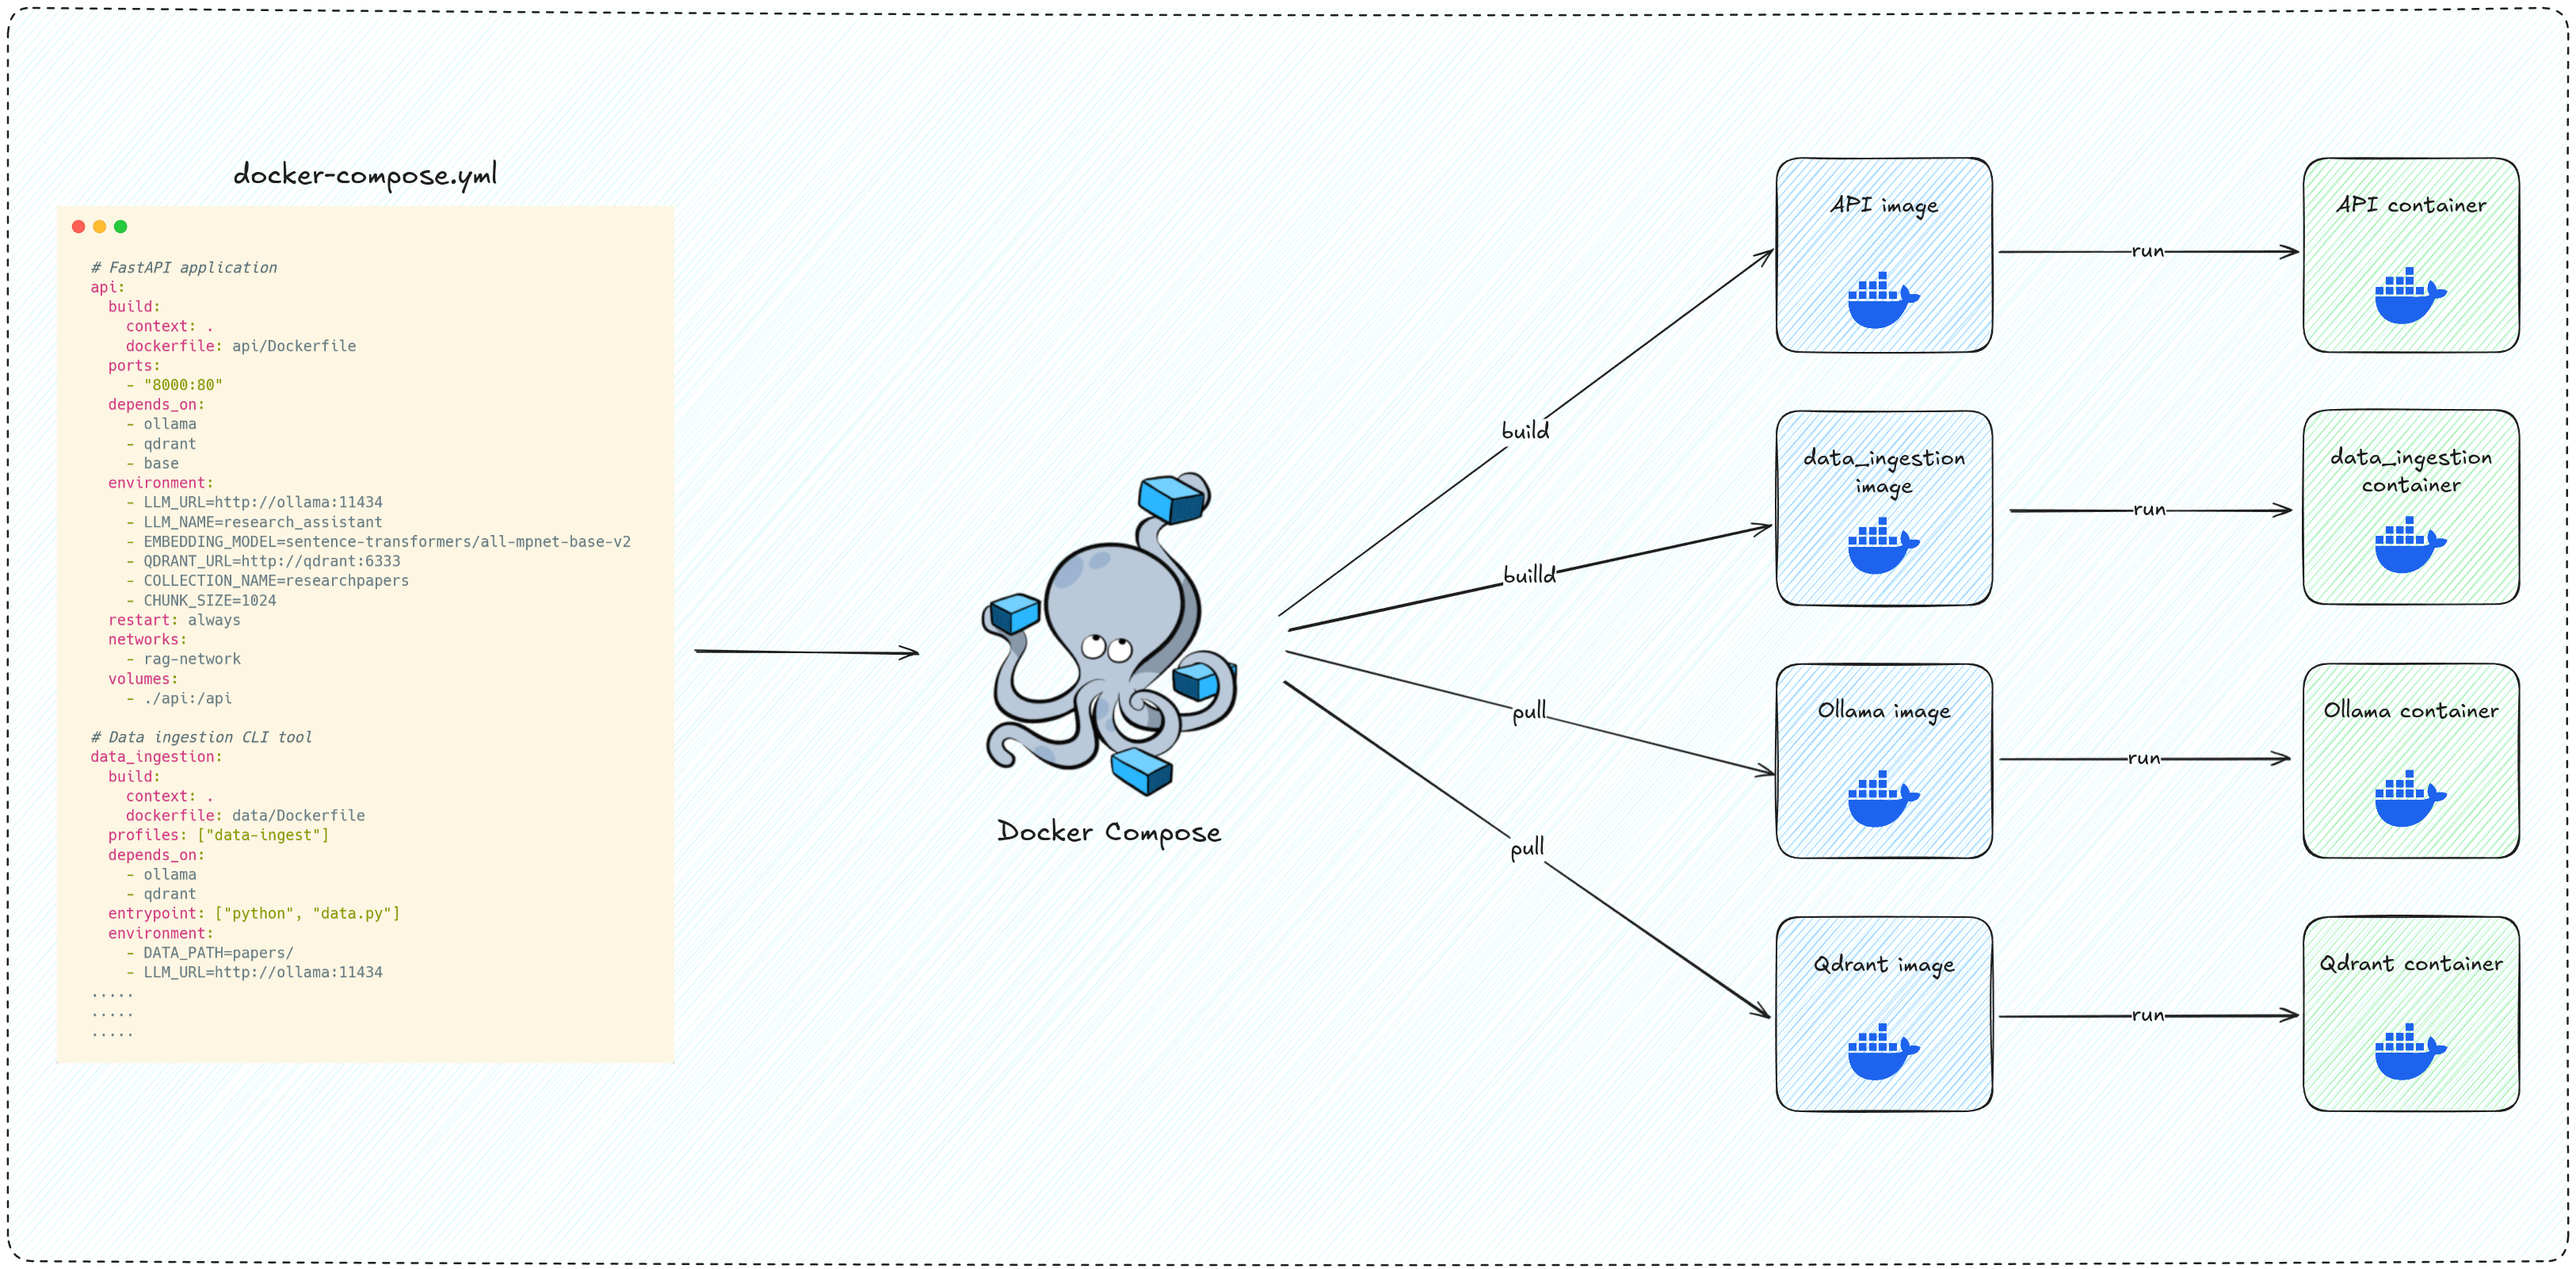
In this section, we’ll define a docker-compose.yml file that orchestrates the entire setup, allowing us to spin up the FastAPI API, Ollama model server, Qdrant vector database, and our data ingestion tool all at once with a single command.
Building the Base image
1
2
3
4
5
6
services:
  base:
    build:
      context: .
      dockerfile: Dockerfile.base
    image: rag-base-image
This service builds a base image that contains all shared dependencies across our project, tagged rag-base-image. The api and data_ingestion services build on top of it (FROM rag-base-image in their Dockerfiles).
This approach keeps the builds fast by avoiding repeated dependency installations across services.
Api service
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
  api:
    build:
      context: .
      dockerfile: api/Dockerfile
      additional_contexts:
        rag-base-image: service:base
    ports:
      - "8000:80"
    depends_on:
      - ollama
      - qdrant
    environment:
      - LLM_URL=http://ollama:11434
      - LLM_NAME=research_assistant
      - EMBEDDING_MODEL=sentence-transformers/all-mpnet-base-v2
      - QDRANT_URL=http://qdrant:6333
      - COLLECTION_NAME=researchpapers
      - CHUNK_SIZE=1024
    restart: always
    networks:
      - rag-network
    volumes:
      - ./api:/api
This runs our main RAG API built with FastAPI, exposing it on localhost:8000.
additional_contexts is what ties this image to the base image: whenever the Dockerfile asks for rag-base-image, Compose uses the image built by the base service, and builds base first. Without it, Compose has no way of knowing the two are related (it doesn’t read our Dockerfiles), so it may build both images in parallel. Recent Compose versions do exactly that, and the FROM rag-base-image line then fails with a “pull access denied” error, as Docker tries to download an image called rag-base-image from Docker Hub.
depends_ondoesn’t help with that: it only controls the order in which containers start (here, Ollama and Qdrant are started before the API), not the order in which images are built. It also doesn’t wait for a service to be ready, only for its container to start.
Data ingestion tool
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
  data_ingestion:
    build:
      context: .
      dockerfile: data/Dockerfile
      additional_contexts:
        rag-base-image: service:base
    profiles: ["data-ingest"]
    depends_on:
      - ollama
      - qdrant
    environment:
      - DATA_PATH=papers/
      - LLM_URL=http://ollama:11434
      - LLM_NAME=research_assistant
      - EMBEDDING_MODEL=sentence-transformers/all-mpnet-base-v2
      - QDRANT_URL=http://qdrant:6333
      - COLLECTION_NAME=researchpapers
      - CHUNK_SIZE=1024
    networks:
      - rag-network
    volumes:
      - ./papers:/app/papers
This is a one-off job used to load and embed documents into Qdrant, so we don’t need this container to be continuously running: we start it, it loads and embeds the documents into our vector database, and then it exits.
That’s what the data-ingest profile is for: services with a profile are skipped by project-wide commands like docker compose up or docker compose build, unless the profile is enabled with --profile data-ingest. Running the service by name with docker compose run data_ingestion works regardless.
Qdrant service
1
2
3
4
5
6
7
8
  qdrant:
    image: qdrant/qdrant
    ports:
      - "6333:6333"
    volumes:
      - ~/qdrant_storage:/qdrant/storage:z
    networks:
      - rag-network
Runs the Qdrant vector DB, which stores the chunked and embedded documents locally. It exposes port 6333 and persists data using the specified volume on our machine.
Ollama service
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
  ollama:
    image: ollama/ollama:latest
    pull_policy: always
    container_name: ollama
    volumes:
      - ./ollama:/model_files
      - ./ollama:/root/.ollama
    tty: true
    entrypoint: ["/bin/sh", "./model_files/run_ollama.sh"]
    environment:
      - LLM_NAME=research_assistant
    restart: always
    extra_hosts:
      - host.docker.internal:host-gateway

    # Uncomment to run Ollama on an NVIDIA GPU (requires the NVIDIA Container Toolkit).
    # Leave commented on machines without one (e.g. Macs): Ollama then runs on CPU.
    # deploy:
    #   resources:
    #     reservations:
    #       devices:
    #         - driver: nvidia
    #           count: all
    #           capabilities: [gpu]
    ports:
      - "11434:11434"
    networks:
      - rag-network
This runs the Ollama LLM server locally and exposes it on port 11434. It runs a custom run_ollama.sh script to load the desired model.
1
2
3
4
5
6
7
8
9
10
11
12
13
#!/bin/bash

echo "Starting Ollama server..."
ollama serve &  # Start Ollama in the background

echo "Ollama is ready, creating the model..."

if [ -z "$LLM_NAME" ]; then
  echo "Error: LLM_NAME environment variable is not set."
  exit 1
fi
ollama create $LLM_NAME -f ./model_files/Modelfile
ollama run $LLM_NAME
The commented-out deploy block gives Ollama access to an NVIDIA GPU. It’s a hard reservation, not a preference: on a machine without an NVIDIA GPU and the NVIDIA Container Toolkit, the container refuses to start (could not select device driver "nvidia" with capabilities: [[gpu]]) instead of falling back to the CPU. That’s why it’s commented out by default; uncomment it if you have a compatible GPU. For more details, see the official guide: Enable GPU access with Docker Compose
On a Mac, Docker can’t use the Apple GPU, so Ollama runs on CPU inside the container, and a query can take a minute or more.
Network and Volumes
1
2
3
4
5
6
7
networks:
  rag-network:
    driver: bridge

volumes:
  qdrant_storage:
  ollama:
rag-network: A shared bridge network so services can talk to each other by name, eg:ollama:11434volumes: Declares named volumes. Note that our services don’t actually use them: Qdrant and Ollama store their data in bind mounts, folders on our own machine (~/qdrant_storageand./ollama), which is what keeps the data between runs.
You can find the full docker-compose.yml file here: docker-compose.yml
What’s left to do now is build the images and run the containers. First, build all three images (--profile data-ingest includes the data ingestion image):
1
docker compose --profile data-ingest build
Start Qdrant and Ollama in the background:
1
docker compose up -d qdrant ollama
Ingest some documents into our vector database:
1
docker compose run --rm data_ingestion --query "LLMs" --max 10 --ingest
Then start the API:
1
docker compose up api
Ingest at least once before starting the API. The API inspects the Qdrant collection when it starts, and if the collection doesn’t exist yet, queries fail with
Not existing vector name error: text-dense. If that happens, rundocker compose restart api. Ingesting more documents later doesn’t require a restart.
We can now query the API:
1
2
3
curl -X POST http://localhost:8000/api/search \
  -H "Content-Type: application/json" \
  -d '{"query": "What are the main findings?", "similarity_top_k": 2}'
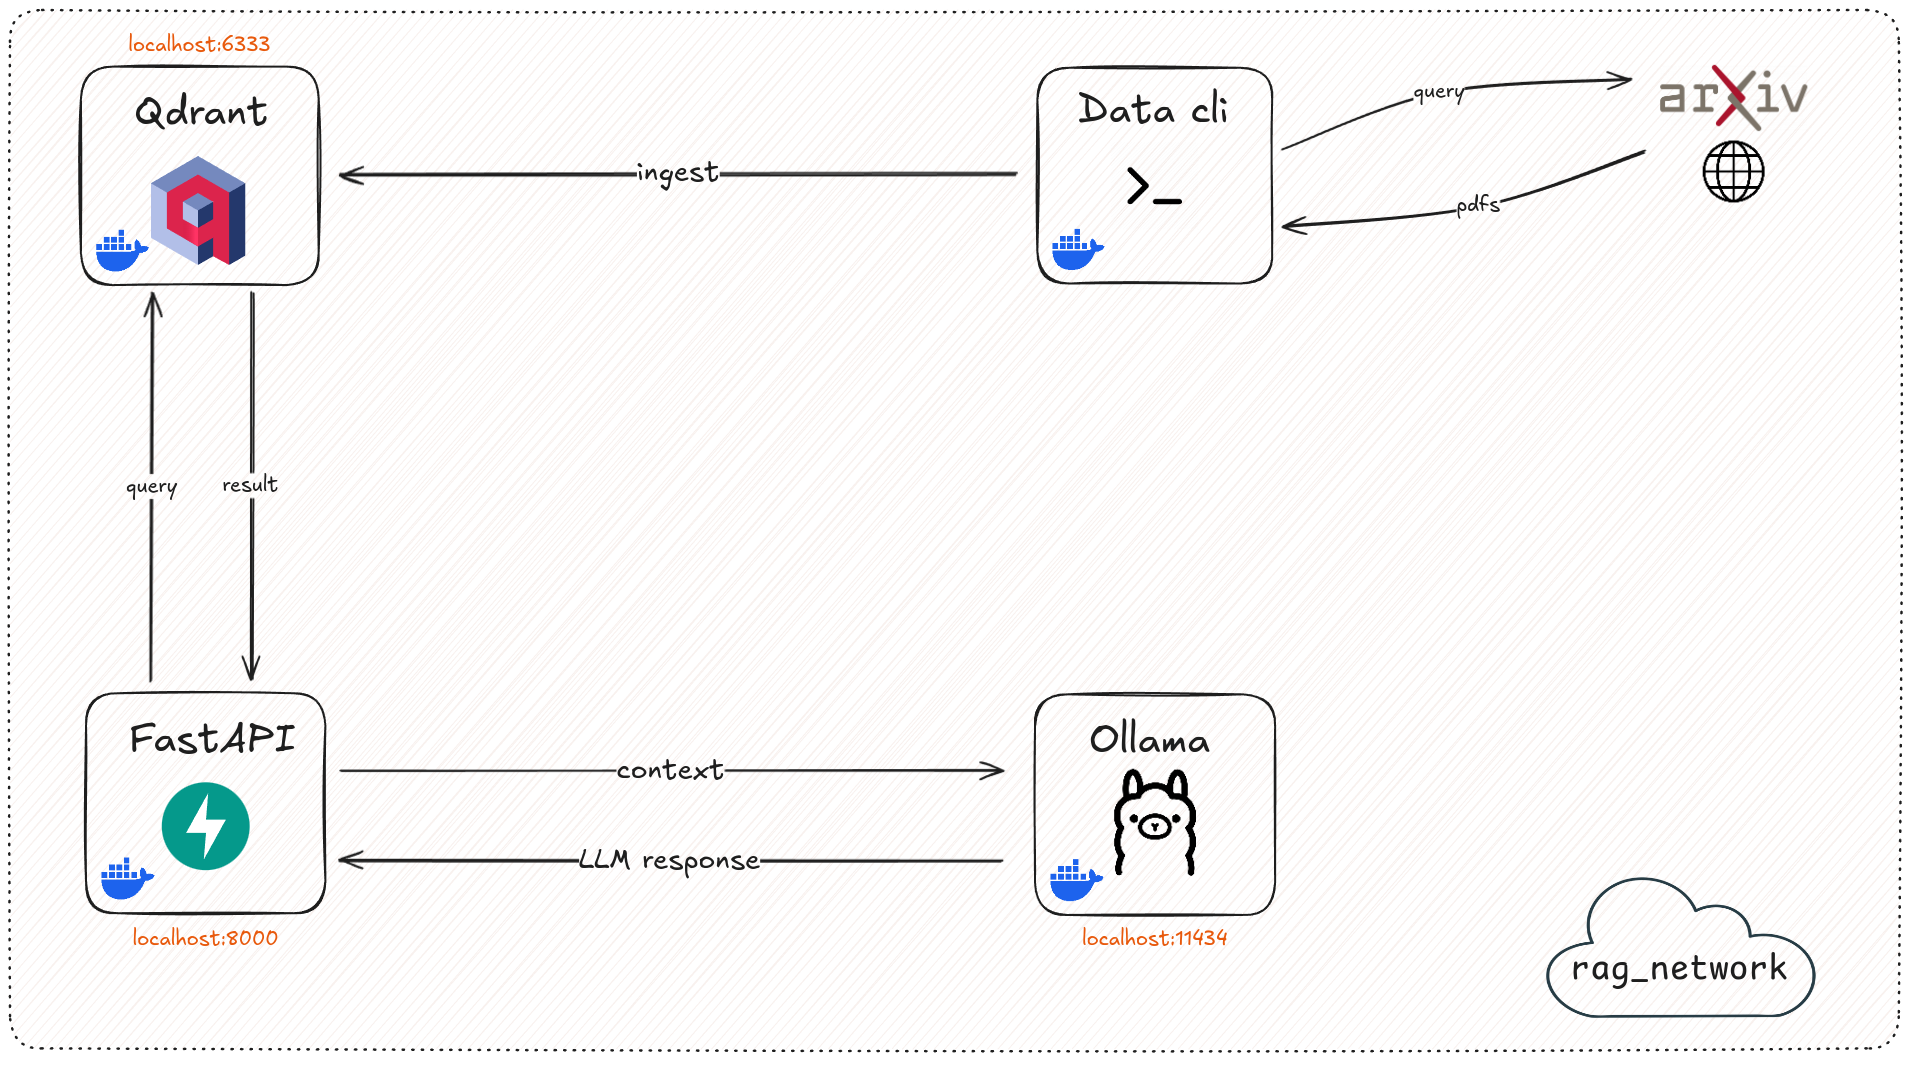
Api is now running on: http://localhost:8000/docs
Ollama: http://localhost:11434/
Qdrant ui: http://localhost:6333/dashboard#/collections
Finally, to stop all running containers and networks started by Docker Compose:
1
docker compose down
docker compose down --volumes would not reset our data here, since it only removes named volumes, and our data lives in bind mounts. To start over from scratch, delete those folders after stopping the containers: ~/qdrant_storage for the stored vectors and ./papers for the downloaded PDFs. Keep ./ollama, unless you want to download the model again.
Conclusion
In this article, we learned how to dockerize a RAG application built with FastAPI, Llamaindex, Qdrant and locally served model via Ollama.
Explore the full project on Github repository